Preview
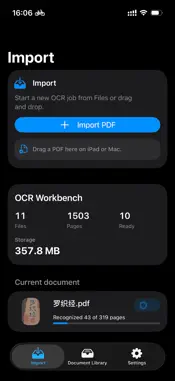
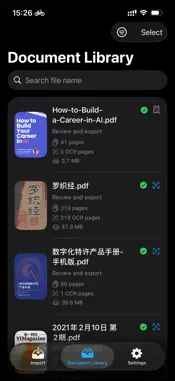
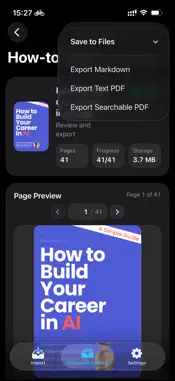

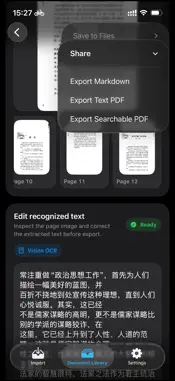


Description
PDF2Words helps you turn scanned PDFs, image-based PDFs, and document copies into text you can search, copy, and export. It fits lecture notes, contracts, scanned books, research material, and archived records that need cleanup before reuse. What you can do with PDF2Words - Import scanned or image-based PDFs - Automatically detect pages that need OCR - Review recognized text page by page against the original page - Export as Markdown, text-only PDF, or searchable PDF - Reuse embedded text when the source PDF already contains selectable text Common use cases - Convert lecture notes and scanned books into reusable text - Make contracts, reports, and research material searchable - Organize archive scans for lookup and filing - Export PDF content to Markdown for note-taking, drafting, or excerpts Product notes - Designed to rely on Apple's on-device OCR where supported - No need to send files to third-party AI services - Available on iPhone, iPad, and Mac - Recognition quality depends on scan quality and the text recognition support available on your device and OS Privacy Policy: https://wonderfulsuccess.github.io/PDF2Words-site/privacy.html Terms of Use (EULA): https://www.apple.com/legal/internet-services/itunes/dev/stdeula/
Technical Analysis
Package Overview Basic metadata
Bundle ID
javsnice.pdfOCR Current Version 1.0
Minimum iOS 18.0
Package Size App Store Size
Package Metadata 0 / 1 version records
Detailed binary, privacy manifest, framework, and Info.plist results have not been indexed for this package yet. The verified App Store and archive metadata above remains available.
Developer Information
Known Version Records
0 version records with stored package metadata • 1 known version records
Stored metadata does not guarantee a package is currently available to download.
| Details | Version / IDs | Version date | Action |
|---|---|---|---|
| Not archived | App Store ID: 884298361 | Unknown | Request Version |