Preview

Description
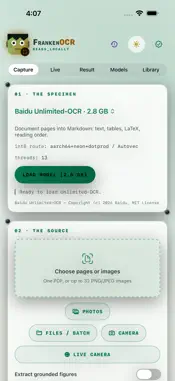
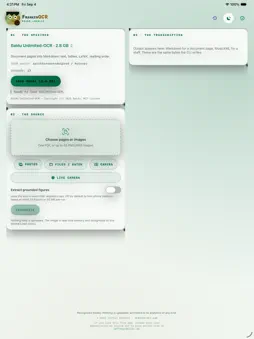
Extract text from an image or scanned PDF without uploading the document. FrankenOCR uses the same pure-Rust Unlimited-OCR engine as the FrankenOCR command-line project. Choose a photo, file, camera capture, tall scrolling screenshot, or scanned PDF. The app reads the input in memory and produces structured Markdown on the device. The flagship recognition path uses a downloaded, verified Baidu Unlimited-OCR model for careful document extraction. Tall screenshots are divided with overlap-aware smart cuts, while PDF pages are processed as a document and low-yield pages are called out instead of silently disappearing. Live Camera mode uses Apple's on-device Vision text recognition for speed. It is less accurate than the flagship FrankenOCR model, and the app labels that tradeoff clearly. Recognized words flow from their camera positions into the capture tray as the view updates. The current app ships one flagship model: Unlimited-OCR. It does not claim to include GOT-OCR2, SmolVLM2, OneChart, or a music-recognition model. Images, PDFs, camera frames, and recognized text stay on the device. Network access is used only to download the static flagship model files.
What's New
Version 1.2 2026-09-05
Process full multi-image and PDF batches with shared document context across pages. Import through Photos, Files, camera, or the share extension; preserve resul... Technical Analysis
Package Overview Basic metadata
Bundle ID
com.frankenocr.FrankenOCR Current Version 1.2
Minimum iOS 17.0
Package Size App Store Size
Package Metadata 0 / 0 version records
Detailed binary, privacy manifest, framework, and Info.plist results have not been indexed for this package yet. The verified App Store and archive metadata above remains available.
Developer Information
Known Version Records
0 version records with stored package metadata
Stored metadata does not guarantee a package is currently available to download.
| Details | Version / IDs | Version date | Action |
|---|