Preview





Description
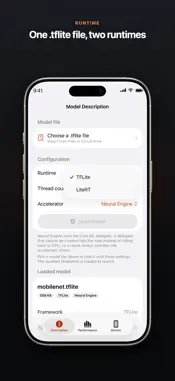
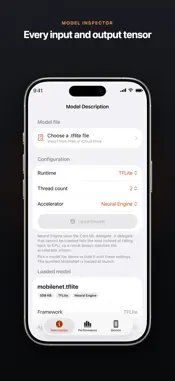
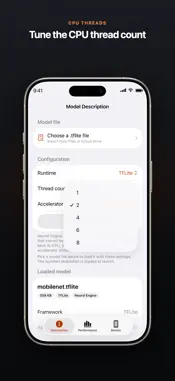
How fast does your .tflite model actually run on this iPhone? Pick CPU, GPU or Neural Engine. Get real latency and QPS. No Mac, no Xcode project, no Bazel build, no cloud, no account. Open a .tflite file from the Files app, pick an accelerator, run it. A real measurement on the exact device you care about, in about a minute — no Bazel workspace, no benchmark tool built from source. PICK THE ACCELERATOR - Neural Engine — attaches the Core ML delegate, so supported operators run on the Apple Neural Engine - GPU — attaches the GPU delegate, backed by Metal - CPU — the plain interpreter, with a thread count you choose: 1, 2, 4, 6 or 8 One configuration per run: run it, change the delegate or thread count, load it again, compare the numbers yourself. WHAT YOU GET - Latency: mean, min and max, in milliseconds - Queries per second - Total queries completed and total run duration - A query count you set per run, from 50 to 5,000 invocations Mean, min and max time the model inference call only — no pre-processing, no post-processing. Duration covers the whole loop. The screen stays awake during a run. WHAT YOU SEE ABOUT THE MODEL - Every input and output tensor: index, name, shape and data type (uInt8, int32, float16, float32 and the rest) - Model file size and framework - Live app memory usage against the memory available to the app, refreshed while the model runs - A device tab with model identifier, system version, disk space, and the exact TensorFlow Lite runtime version this build links against A MobileNet model ships in the app and loads on launch, so you see a real measurement before importing your own. READ THIS BEFORE YOU TRUST A NUMBER Inference runs on a zeroed dummy input. The app fills every input tensor with zeros and invokes the model, so what you measure is the compute cost of the graph on the accelerator you picked — latency and throughput, nothing else. It is not an accuracy test. It will not tell you whether your model gives the correct answer, and it does not show output tensor values. Ask it "how fast", not "how correct". What it does not do, stated up front: no side-by-side accelerator comparison in one run, no per-layer or per-operator profiling, no result export, no image or real-data input. It opens .tflite files only. PRIVACY Your model never leaves the device. Loading, inspection, inference and timing all happen locally on your iPhone or iPad. No account, no sign-in — your models and your results are never uploaded. TensorFlow Lite is now called LiteRT; the format and the .tflite extension are unchanged. TensorFlow, the TensorFlow logo and any related marks are trademarks of Google Inc. Not affiliated with or endorsed by Google.
What's New
Version 2.0 2026-09-11
Now available in German, Japanese, Korean and Simplified Chinese. LiteRT v2 joins TensorFlow Lite as a second inference runtime. Pick the engine on the Model D... Technical Analysis
Package Overview Basic metadata
Bundle ID
com.anh.ios.MLBenchmark Current Version 2.0
Minimum iOS 16.0
Package Size App Store Size
Package Metadata 1 / 3 version records
Detailed binary, privacy manifest, framework, and Info.plist results have not been indexed for this package yet. The verified App Store and archive metadata above remains available.
Price History (USA store)
2 recorded price change points. These are historical observations, not a guarantee of the current price.
| Recorded at | Price | Currency |
|---|---|---|
| 0.99 | USD | |
| 1.99 | USD |
Known Version Records
1 version record with stored package metadata • 3 known version records
Stored metadata does not guarantee a package is currently available to download.
| Details | Version / IDs | Version date | Action |
|---|---|---|---|
| 10.55 MB | v1.2 App Store ID: 868028890Build: 1.2 | 2024-08-07 13:06:22 | Paid / Arcade |
| Not archived | App Store ID: 859636971 | Unknown | Paid / Arcade |
| Not archived | App Store ID: 852060797 | Unknown | Paid / Arcade |